AI that writes in your brand's voice.
LLM fine-tuning
In simple words: We train an AI model on your own approved examples so its drafts sound like your team and need less editing.
Fine-tune GPT-style APIs, Llama and other open models on your data so the model learns your tone, domain and format.
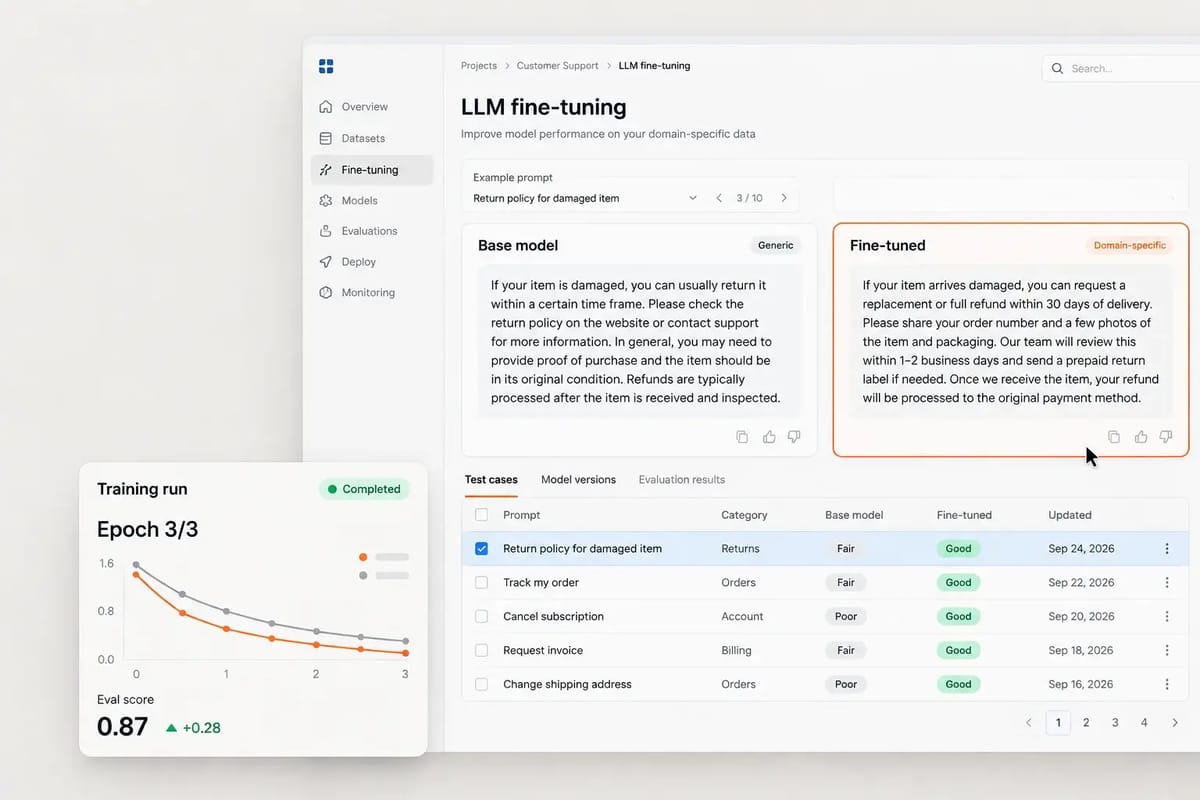
For example: A company's AI replies sounded generic and needed heavy editing. Drafts now need far less editing before sending. See how we did it ↓
The problem
Why teams come to us
Generic model answers miss your tone, terminology and output format, even with careful prompts.
What you get
- Dataset review and training format for your use case
- Dataset cleaning, deduplication and JSONL conversion
- OpenAI fine-tuning or LoRA/QLoRA on open models
- Evaluation against the base model
- Adapters or model files plus a rerunnable notebook
- Docker container or FastAPI inference endpoint
Benefits
What changes for your team
Consistent tone and format
Better domain accuracy
Lower prompt costs
Your own model if you choose open weights
How it works
From first call to working result
- 1
Discovery call
A free 30-minute call to map your goal, sources, volume and where the result should land. NDA on request.
- 2
Sample first
We build a small working sample so you can check fields, format and quality before the full build.
- 3
Build & test
We build the full solution, test it on real data and edge cases, and share progress as we go.
- 4
Deliver & support
You get the result, the source code and short handover notes, plus fixes during the support window.
Example project
A model that writes in the brand voice
- The challenge
- A company's AI replies sounded generic and needed heavy editing.
- What we built
- We cleaned their past approved replies into a training set, fine-tuned a model and compared it with the base model.
- The outcome
- Drafts now need far less editing before sending.
An illustrative example of a typical LLM fine-tuning engagement.
Use cases
Where this helps
Tech stack
Tools we use
FAQ
Questions about LLM fine-tuning
Fine-tuning or RAG: which do I need?
RAG adds knowledge; fine-tuning changes style and format. Many projects use both.
Who pays for GPU or API costs?
You do; we confirm expected costs before training.
Can I host the model myself?
Yes, with open models we deliver files and a Docker container for your GPU server.
Related services
Often combined with
Ready to talk about LLM fine-tuning?
Send a short brief or book a call. A senior engineer replies within a few hours.