All your data, cleaned, in one place.
Data pipelines
In simple words: We gather data from all your sheets, tools and sources every day, remove duplicates, tidy it up and put one clean version where your team works.
Reliable pipelines that collect, clean, validate and load data into your warehouse or database, so every dashboard runs on numbers you can trust.
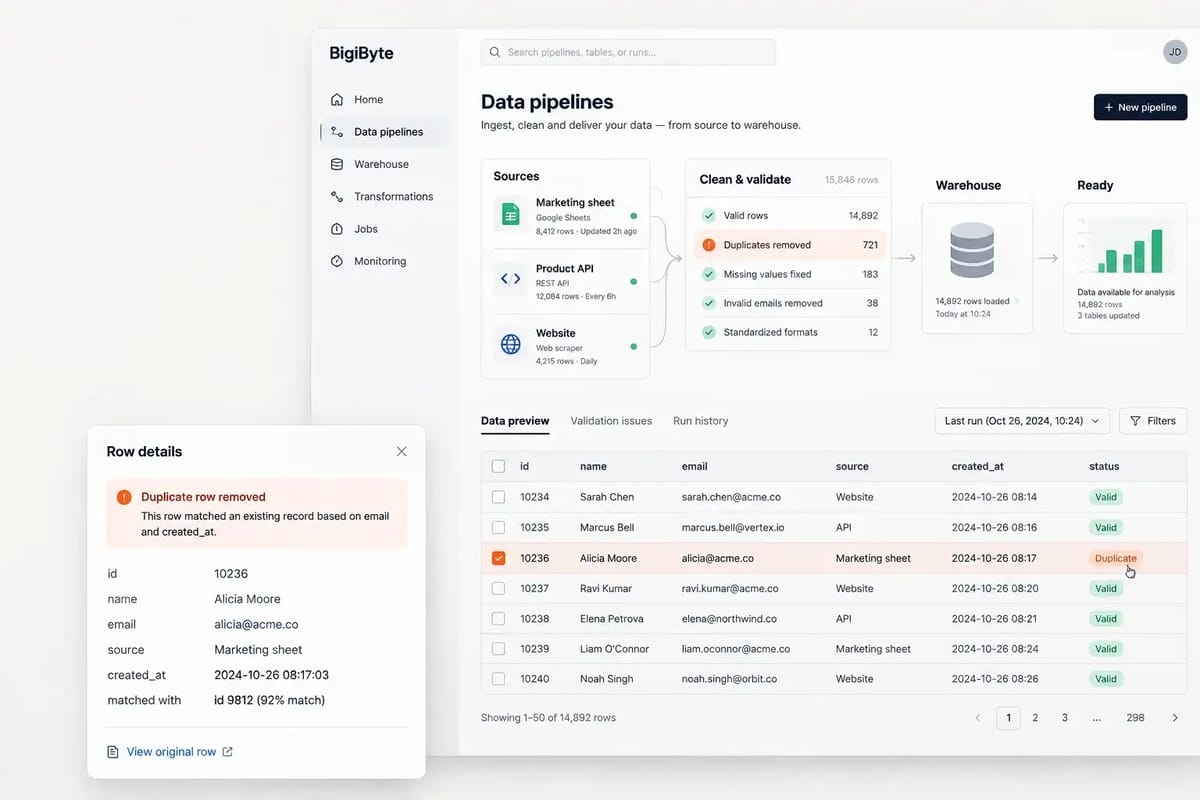
For example: A growth team had leads spread across five spreadsheets and two tools, full of duplicates. The team works from a single trusted list instead of five conflicting ones. See how we did it ↓
The problem
Why teams come to us
Data arrives from many sources in different shapes, with duplicates and gaps. Reports break and nobody trusts the numbers.
What you get
- Pipeline design from source to destination
- Cleaning, normalisation and deduplication
- Validation checks and anomaly alerts
- Loading into PostgreSQL, BigQuery, Snowflake or Sheets
- Scheduling, logging and monitoring
- Documentation of every field
Benefits
What changes for your team
One source of truth
Fewer broken reports
Faster analysis
Easy to add new sources
How it works
From first call to working result
- 1
Discovery call
A free 30-minute call to map your goal, sources, volume and where the result should land. NDA on request.
- 2
Sample first
We build a small working sample so you can check fields, format and quality before the full build.
- 3
Build & test
We build the full solution, test it on real data and edge cases, and share progress as we go.
- 4
Deliver & support
You get the result, the source code and short handover notes, plus fixes during the support window.
Example project
One clean table from five sources
- The challenge
- A growth team had leads spread across five spreadsheets and two tools, full of duplicates.
- What we built
- We built a pipeline that pulls every source nightly, dedupes on company and email, validates fields and loads one clean table into their database.
- The outcome
- The team works from a single trusted list instead of five conflicting ones.
An illustrative example of a typical data pipelines engagement.
Use cases
Where this helps
Tech stack
Tools we use
FAQ
Questions about data pipelines
Which warehouses do you support?
PostgreSQL, BigQuery, Snowflake, MySQL, MongoDB and simpler targets like Google Sheets or Airtable.
How do you catch bad data?
We add schema checks, value ranges and anomaly alerts so problems are flagged before they reach reports.
Can it run on a schedule?
Yes, hourly, daily or triggered by events.
Related services
Often combined with
Ready to talk about data pipelines?
Send a short brief or book a call. A senior engineer replies within a few hours.